Loading live stats

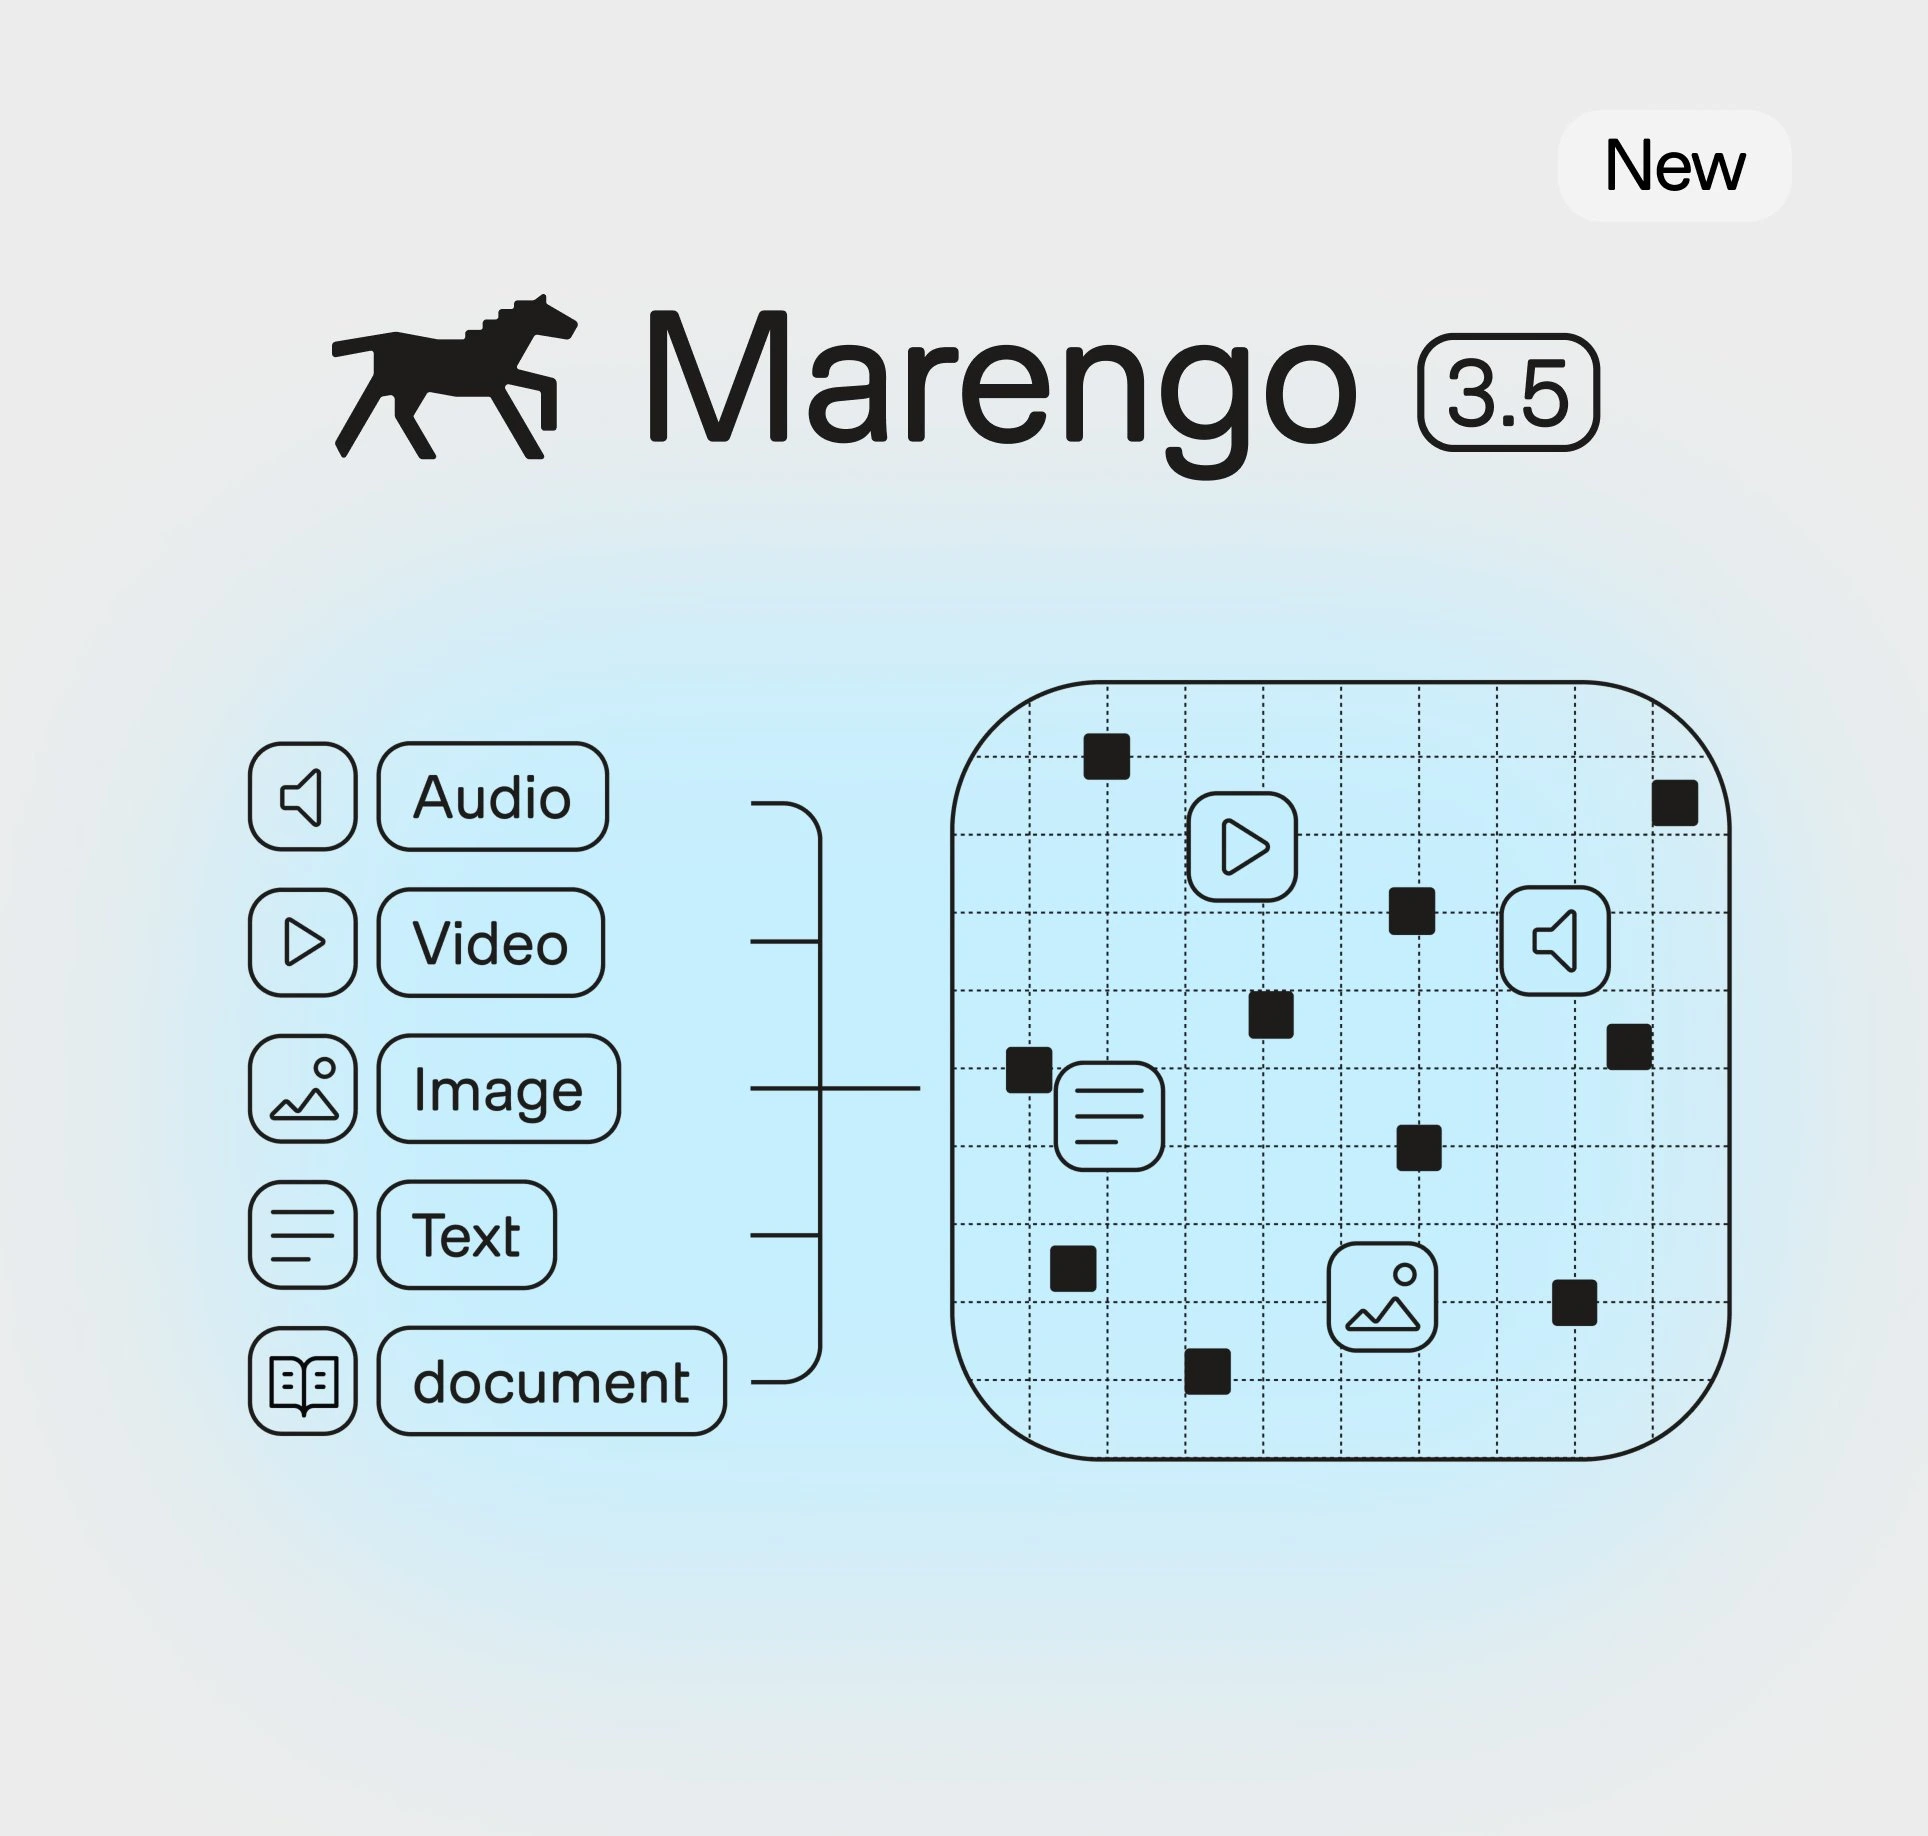
Marengo 3.5 is live. One embedding model for video, audio, images, text, and documents - all in the same semantic space. On text-to-video retrieval, Marengo 3.5 reaches a mean score of 70.57, up 6.29 points from Marengo 3.0. And there’s no duration cap. Learn more➡️

| Category | Update |
|---|---|
| Colors | Colors sampled from the image |
| Posted | |
| Views | 633+ |
| Spotted | |
| Curator | @baseddesigner |


